> ## Documentation Index
> Fetch the complete documentation index at: https://docs.befailproof.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Sentiment analysis
> Find frustrated, confused, and corrective messages with Jev sentiment scores.
Jev scores each message a person sends your agents from 0 to 100 for four feelings — **angry**, **frustrated**, **happy** and **confused** — and three signals about how the agent is doing:
* **Correcting**: the person says the agent got something wrong.
* **Resolved**: the person confirms the agent solved their problem.
* **Doubtful**: the person questions whether the agent's answer is true, or whether it really did the work.
Use sentiment analysis to find conversations where people are losing patience, agents they keep correcting, and replies that land well. This is built-in Jev scoring; you do not need to author an evaluation. For your own fixed-answer question, [create a Jev eval](/evaluations/jev).
Sentiment is off until an admin turns it on for the organization. Jev makes one scoring request per message and receives that message with the agent reply before it. Scoring uses your organization's model budget.
## Turn it on
1. Go to **Administration → Settings**.
2. Under **Human input sentiment**, switch it **on** and save.
Messages from the last day are scored first. After that, new messages are scored within a minute or two of arriving.
## Find a conversation to review
Open **Observe → Sentiment**. Filter by time, environment, agent, or session ID. The header counts messages and sessions, shows how many messages are **flagged**, and names the top signal. A message is flagged when an angry, frustrated, correcting, confused, or doubtful score reaches 35 out of 100.
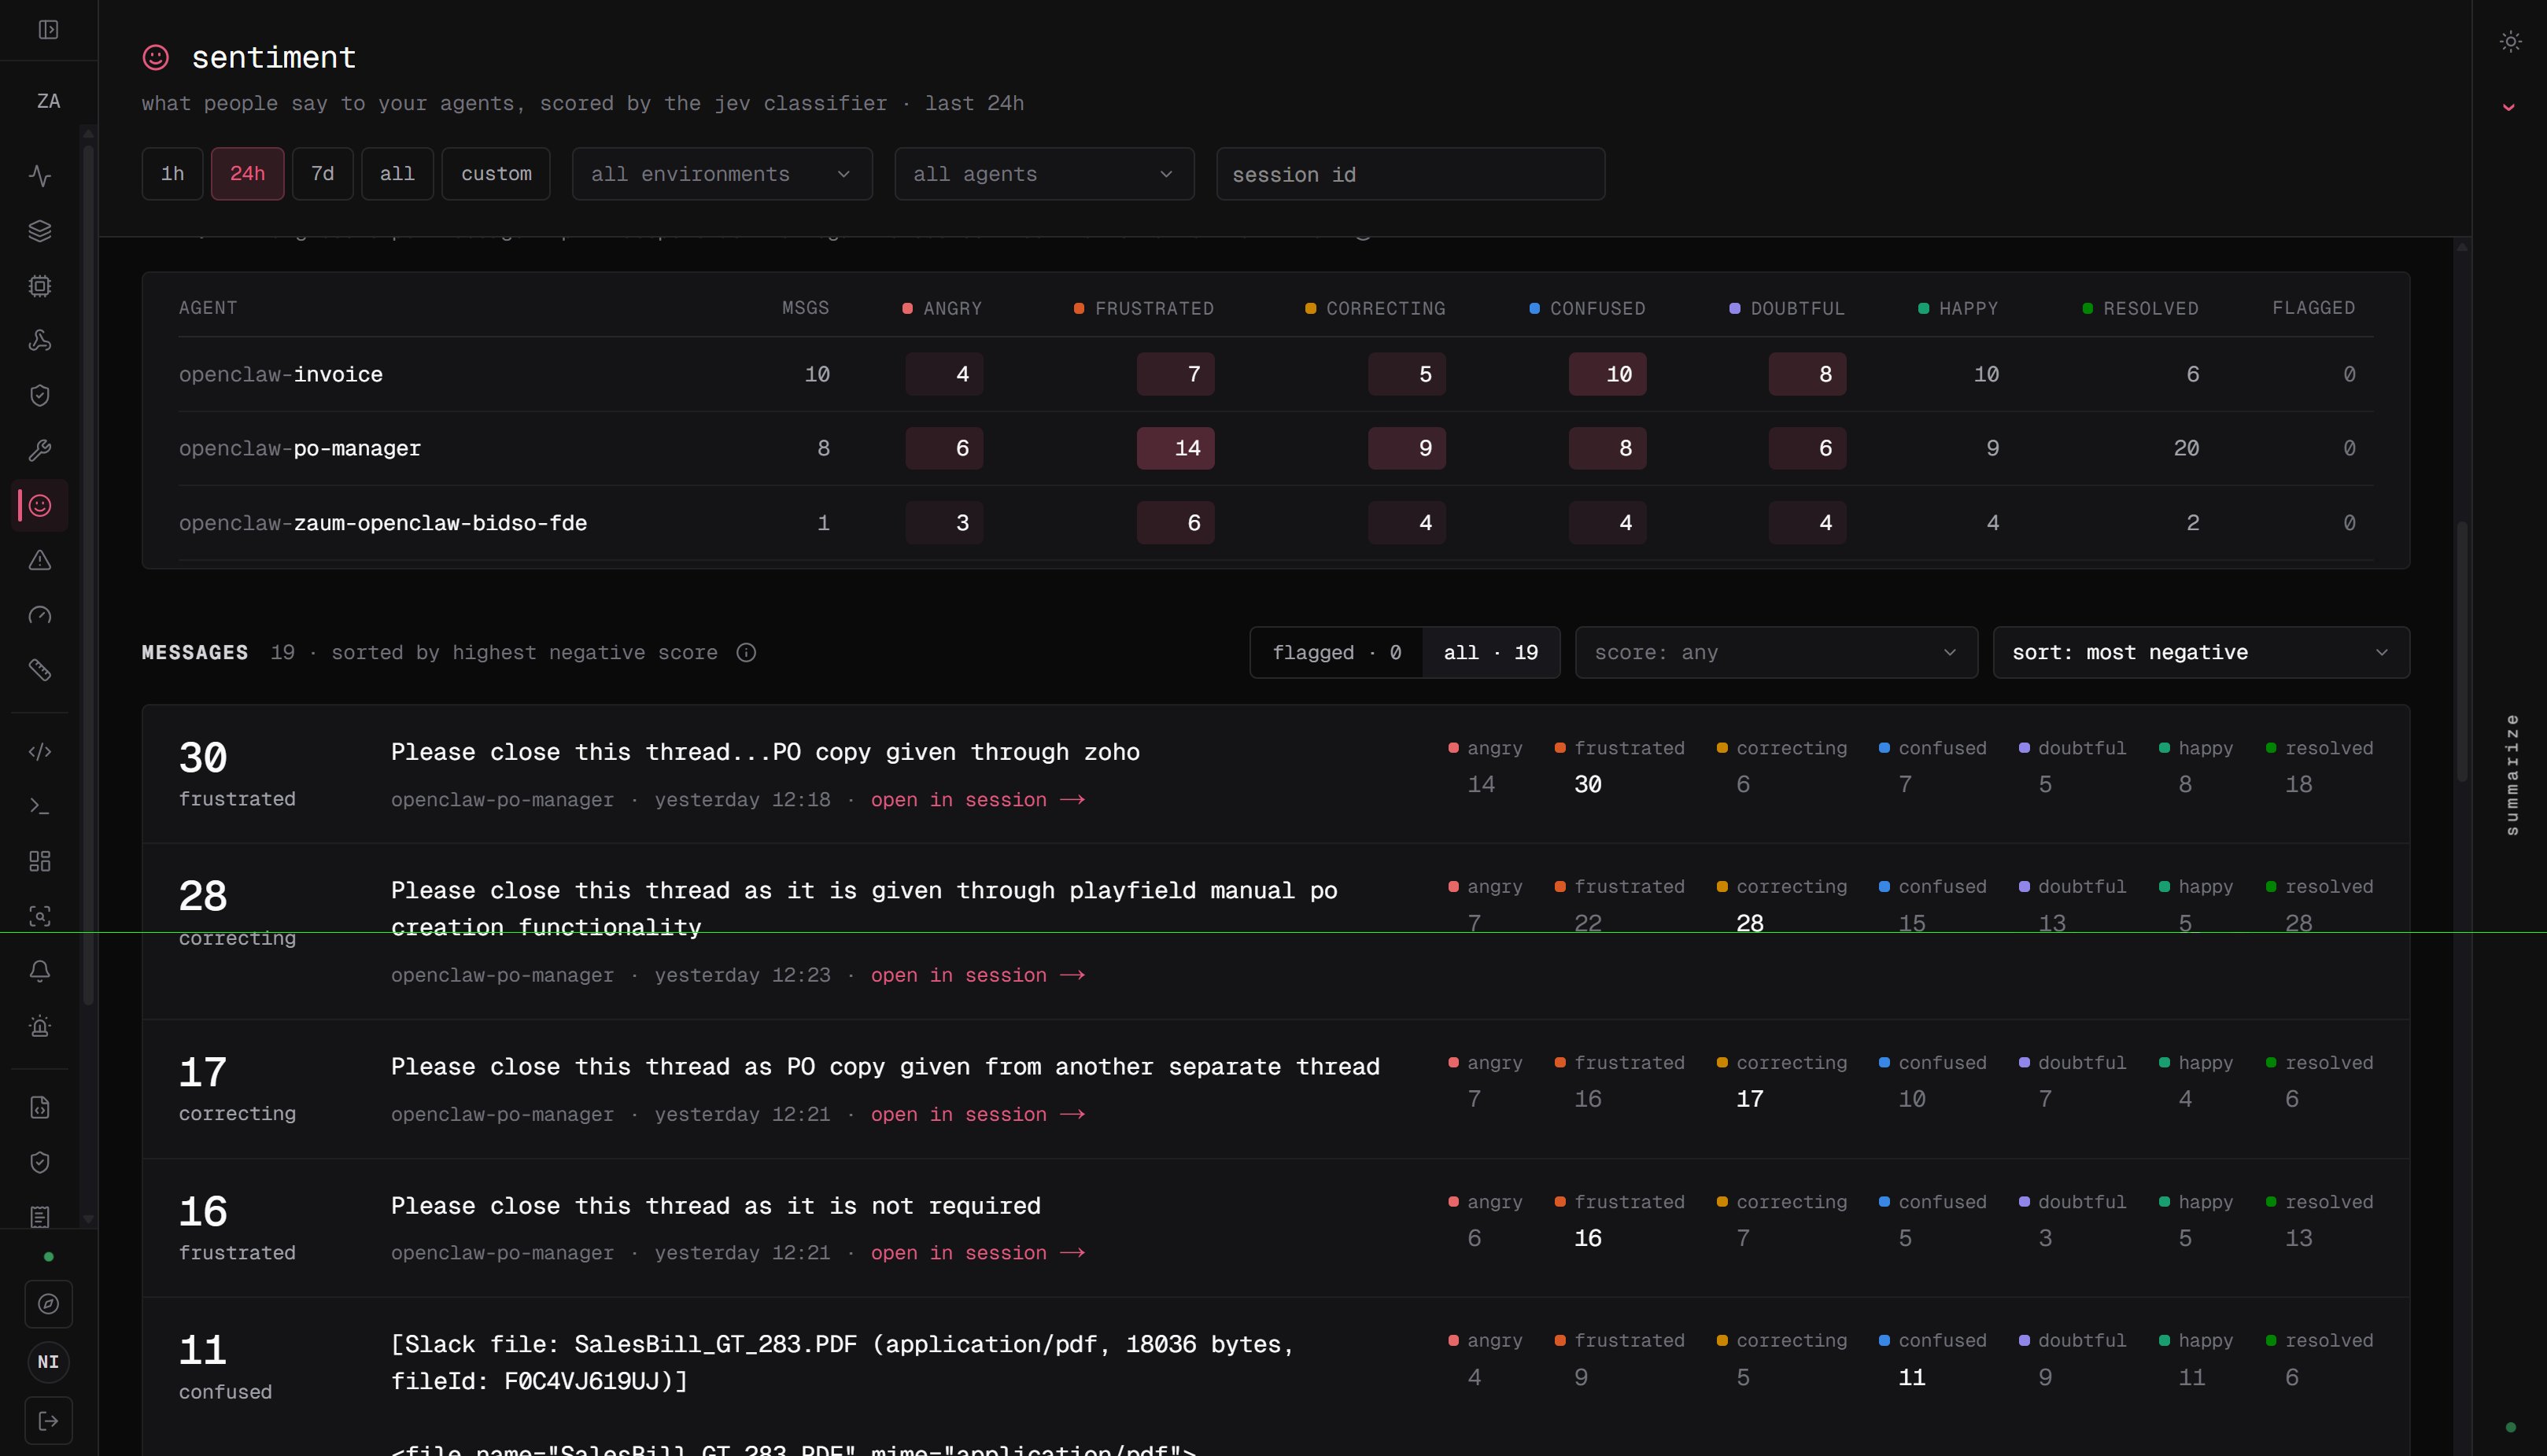
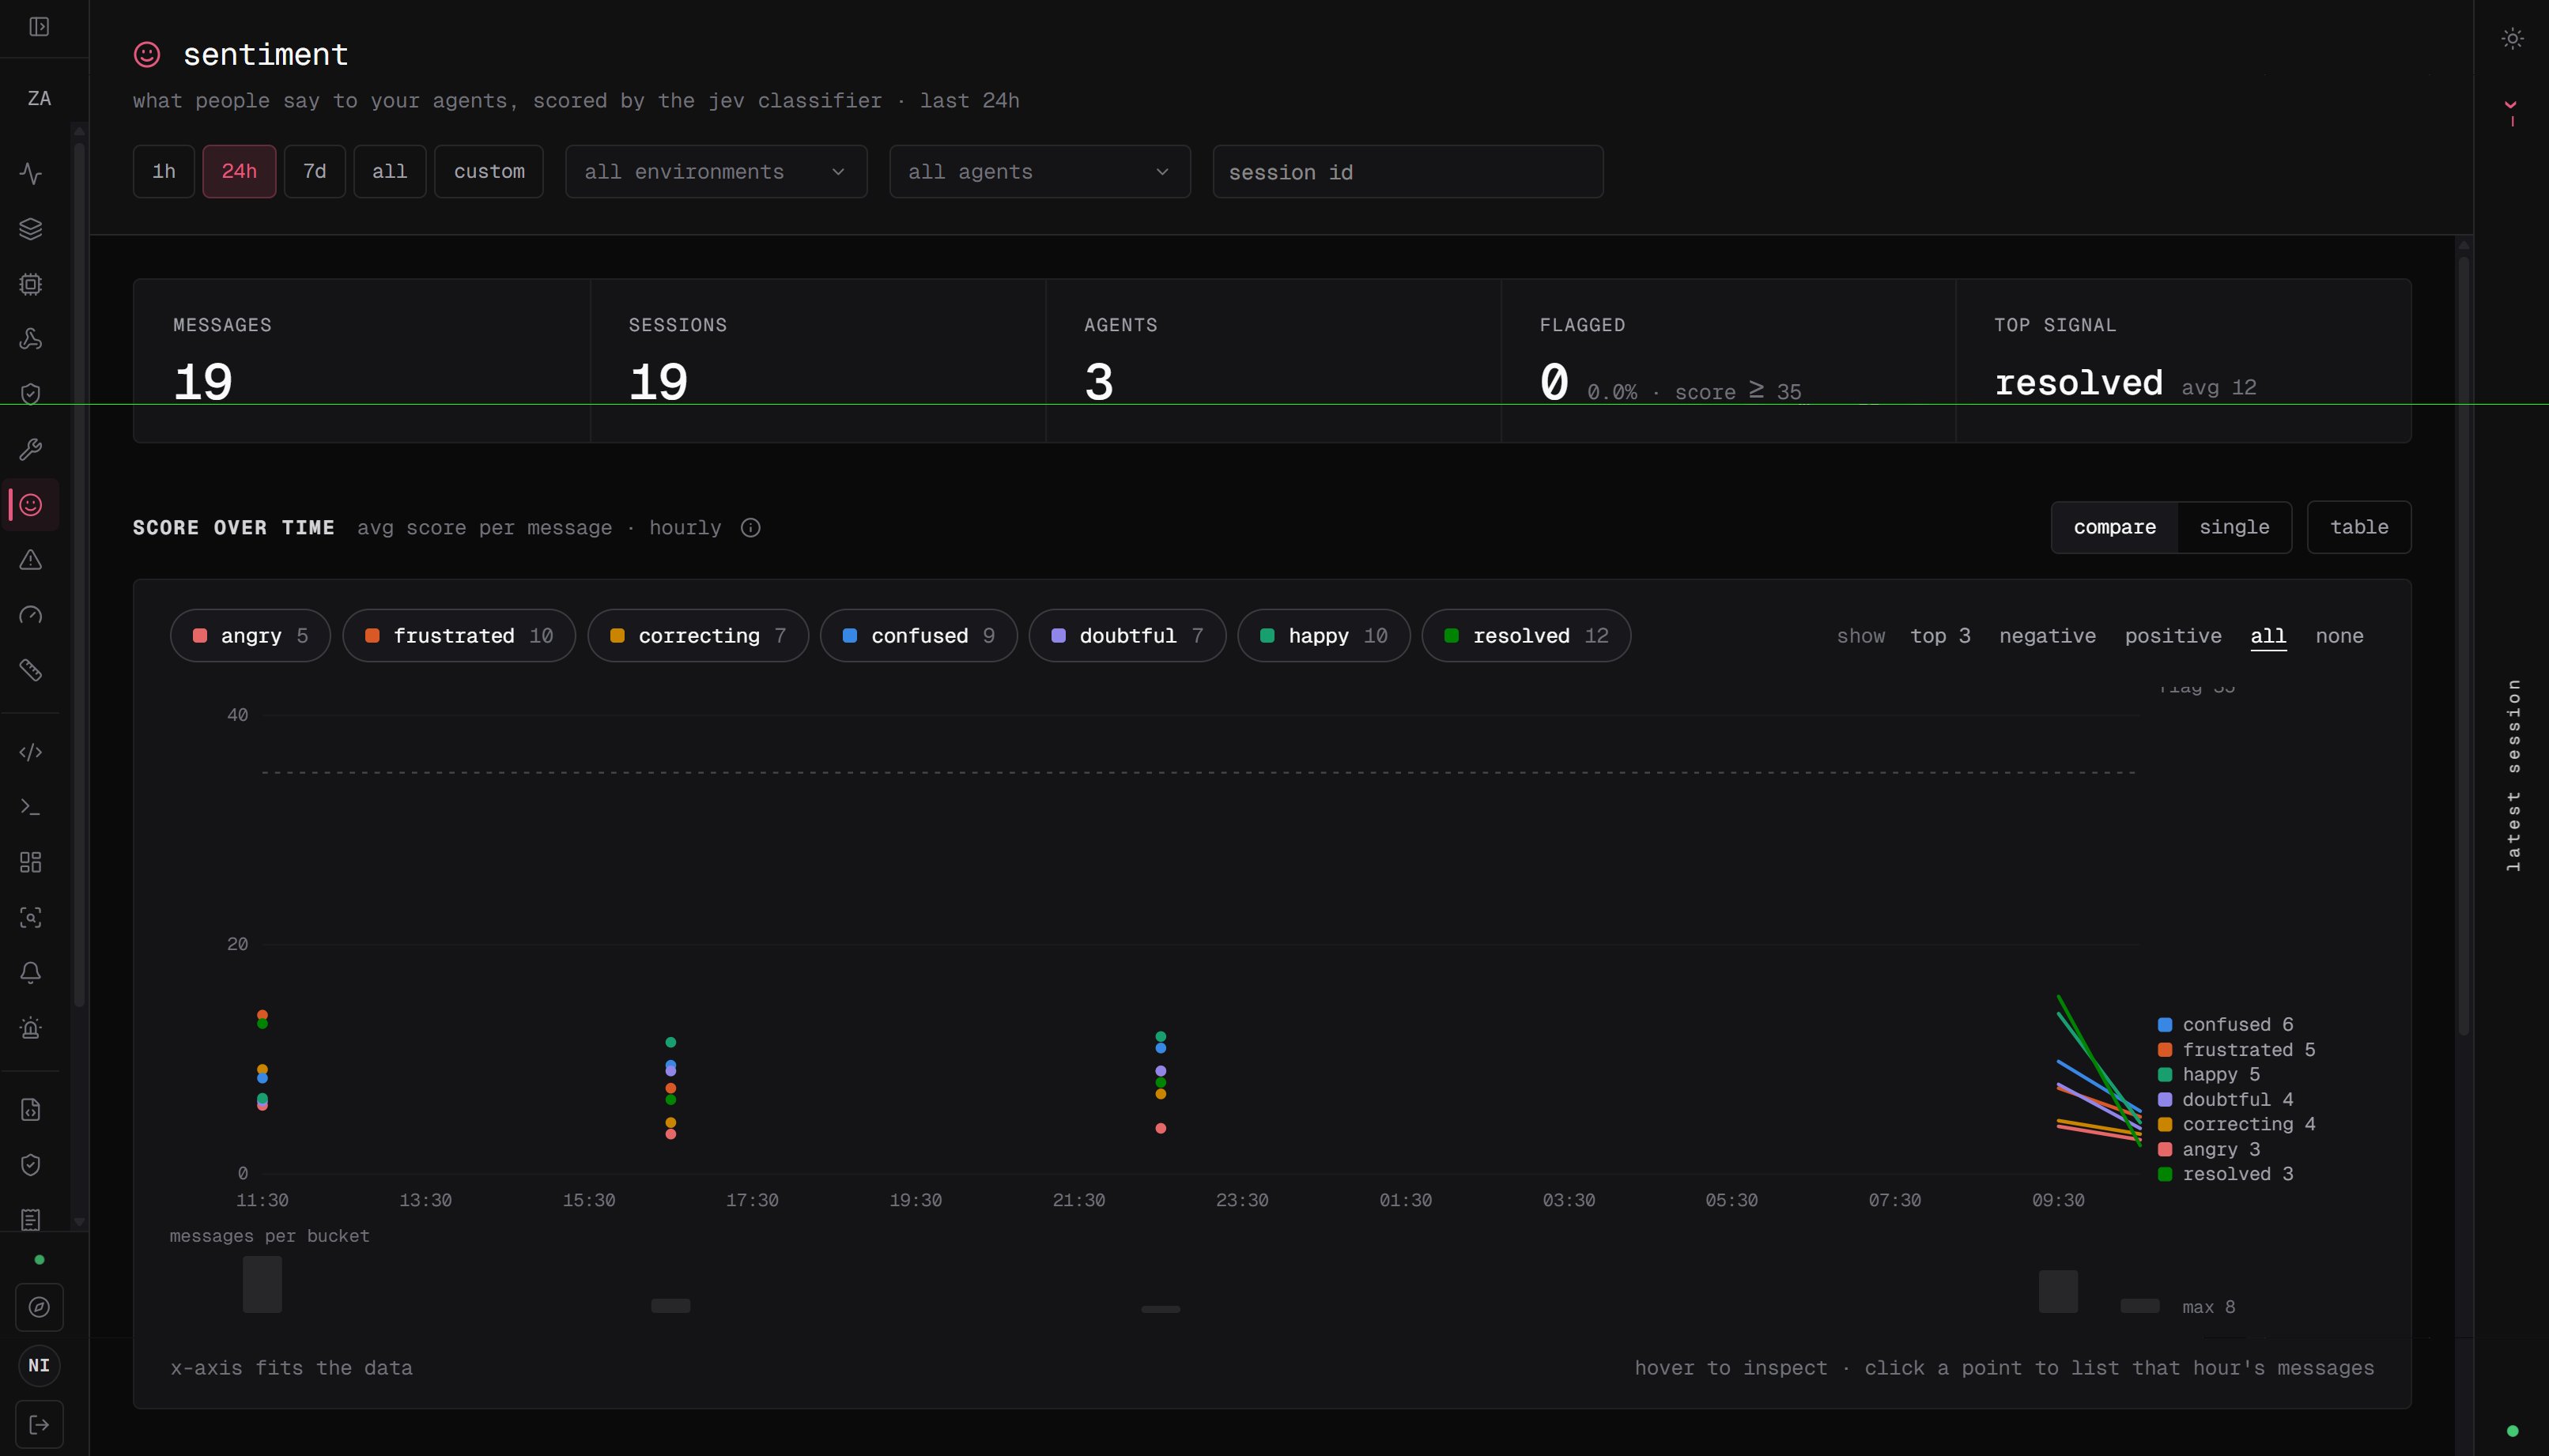 Use **Score over time** to compare signals. Choose the scores to show, then select a point to see that time bucket's messages. The **By agent** table shows where a signal is concentrated. In **Messages**, sort by the strongest negative score or select a single score. Open a message in its session to read the surrounding conversation before deciding what failed.
 ## Which messages are scored
Only messages a person wrote:
* Messages your custom agents record as human input with the SDK.
* Prompts typed into Claude Code, Codex, OpenCode, pi, Hermes and OpenClaw, when session transcripts are sent (the default). Scheduled jobs, injected instructions, sub-agent hand-offs and other text the agent's own runtime writes are not scored. Nor are non-interactive runs such as `claude -p`, `codex exec` and `hermes -z`: a script wrote those prompts, not a person.
Scoring judges the person's own words. A short, blunt instruction such as "fix it" is not counted as anger, and asking a question is not counted as confusion. A new request is not a correction, and thanks on their own do not count as resolved.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.