

Hosted evaluations are small, deterministic Python, written in the dashboard and run on Failproof AI’s evaluator fleet. Heavier logic — an LLM judge, a package, a secret, a network call — runs in your own worker instead.

Draft it from a description

  1. Go to Analyze → eval authoring and select new eval.
  2. Describe what to measure in plain English, or choose from start from an example…, and select draft.
  3. Review the fields and the code it fills in, then test it and deploy it.
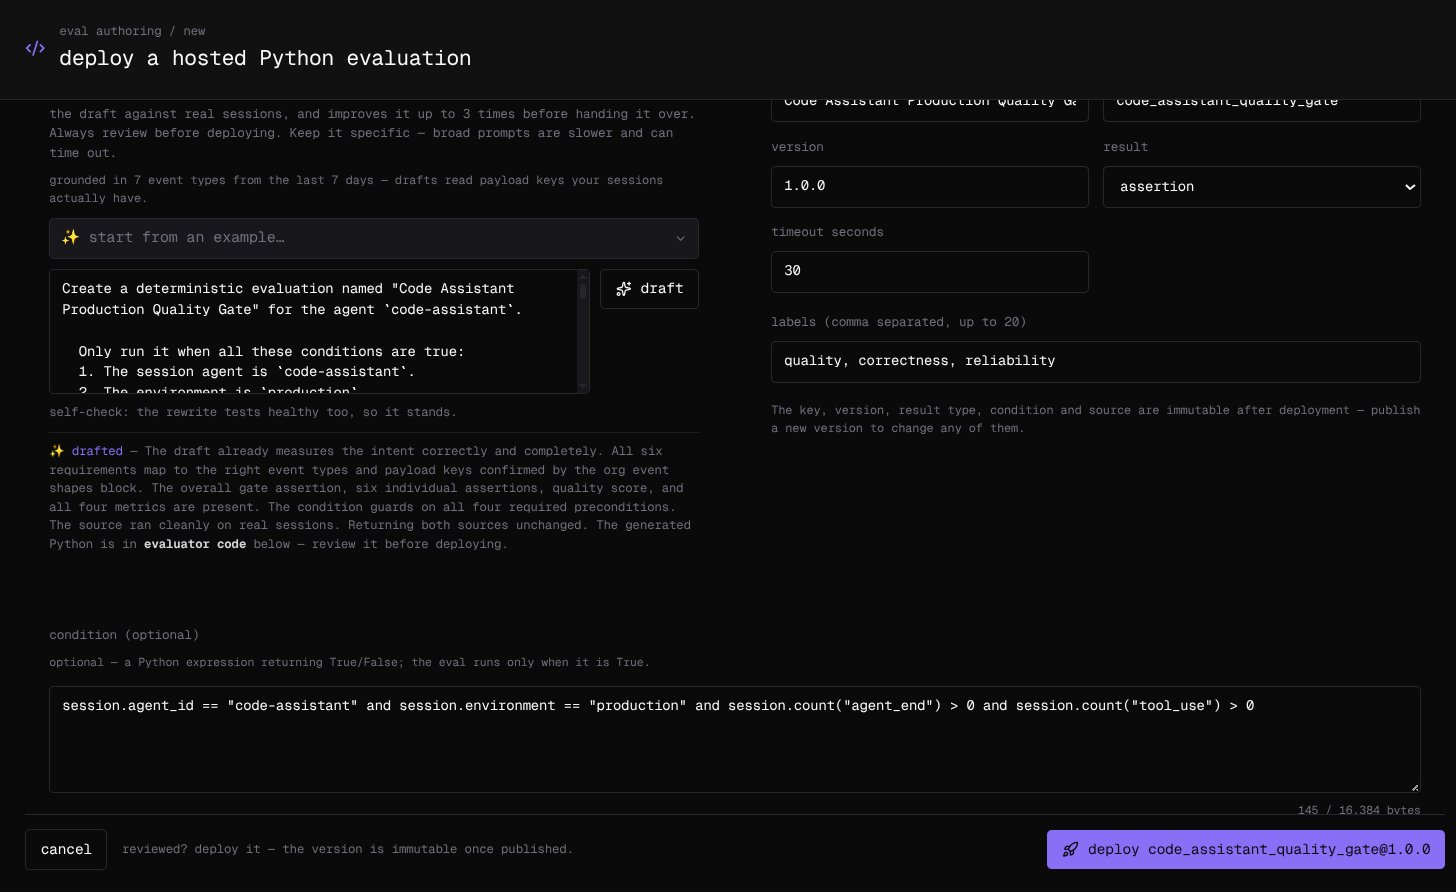
The eval authoring page with a drafted evaluation: the description, the assistant's notes on the draft, and the name, key, version, result, timeout, labels, and condition fields. The draft is grounded in your organization’s own events: the page reads which payload keys your sessions carried over the last seven days, so the code reads keys that exist rather than guesses. Before handing the draft over, the assistant tests it against up to five of your recent sessions, repairs anything it can prove is broken — for up to three rounds — and checks once that the code measures what you asked for. Keep the description specific: broad prompts are slower and can time out. Review the code either way; deploying is never blocked.

Set the fields

Use the condition to scope an evaluation to the agents and environments it is meant for:
The key, version, result type, condition, and code are immutable once deployed: to change any of them, publish a new version. The name, labels, and whether it is enabled stay editable.

Write the code yourself

The evaluator code is one Python expression that returns EvalResult(...), with session in scope. This one scores the share of tool results that came back ok:
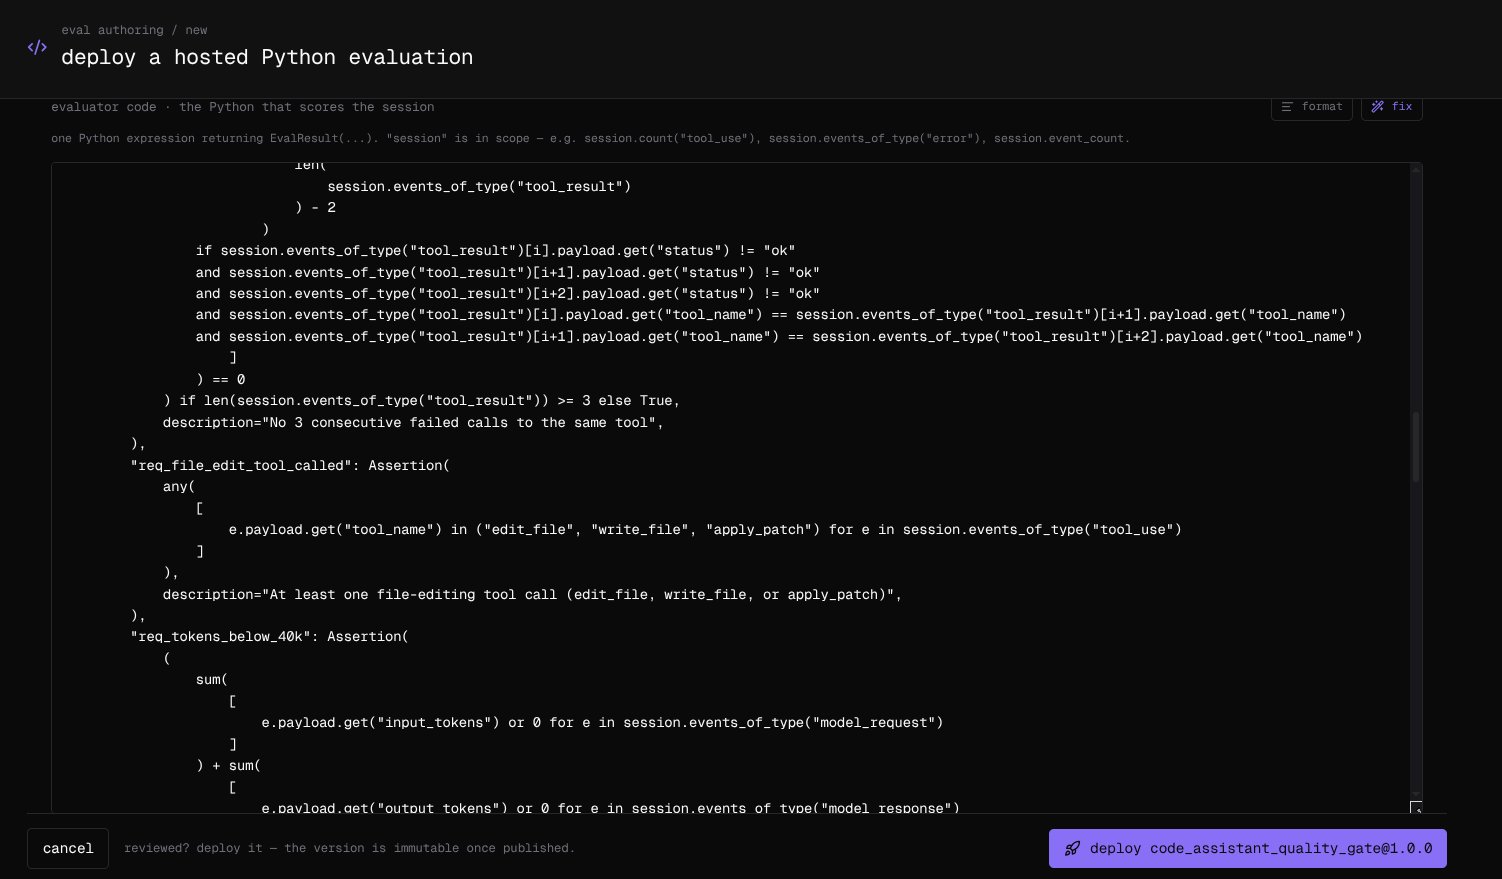
A result leads with the evaluation’s own key, in its declared type: score= for a score evaluation, or a metrics or assertions entry named after the key for a metric or an assertion evaluation. Other metrics and assertions ride along with it, up to 25 results in a run. Nothing else is reachable: no imports, and no attributes beyond that session data and plain string and dictionary methods such as get, lower, and split, which must be called rather than referenced. Payload keys are whatever your agents send — status above is only an example — so read them off a real session. format tidies the code and fix asks the assistant to repair it. The code can be up to 128 KiB, and the condition up to 16 KiB. The evaluator code editor, with format and fix, showing the assertions of a drafted evaluation.
Write it in your own worker

When an evaluation needs a model, a package, a secret, or the network, write it with the Evaluator SDK and run it on your own infrastructure. It uses the same result types, and its results appear beside hosted ones, tagged customer: